Top ASR Models 2027
Introduction
Think about the last time you sent a voice note or switched on auto-captions. You spoke, and within a second the words appeared. Behind that moment, a speech recognition system was listening and typing for you.
This technology is called ASR, or Automatic Speech Recognition, and it forms a core part of modern Speech AI solutions. To a computer, your sentence "Remind me to call Ravi at 5 PM" is only a pattern of sound vibrations stored as numbers. ASR turns those numbers back into the words you meant. Picture an experienced note-taker who listens, understands the context, and writes everything down neatly. Modern ASR does the same, and in clear conditions its output looks almost human.
But not every model is built alike. Some cover many languages, some favour English accuracy, and some are very fast. Here we see how ASR works, then compare seven well-known open models.
How ASR Works
The same model can give two people very different results. Audio quality matters most: a clear microphone in a quiet room beats a crowded street. Accents and dialects come next, since models that have heard many speakers cope better. Vocabulary matters too, because names and technical terms are missed if the model has not seen them.
Key Factors for Accurate Speech Recognition
The same model can give two people very different results. Audio quality matters most: a clear microphone in a quiet room beats a crowded street. Accents and dialects come next, since models that have heard many speakers cope better. Vocabulary matters too, because names and technical terms are missed if the model has not seen them.
Training data and language coverage shape everything. A model excellent in English may be weak elsewhere, which matters in India, where people mix languages in one sentence. Finally, model design and size balance accuracy, speed, and cost. Bigger is often more accurate, but small models can be remarkably fast.
Comparison of Popular ASR Models
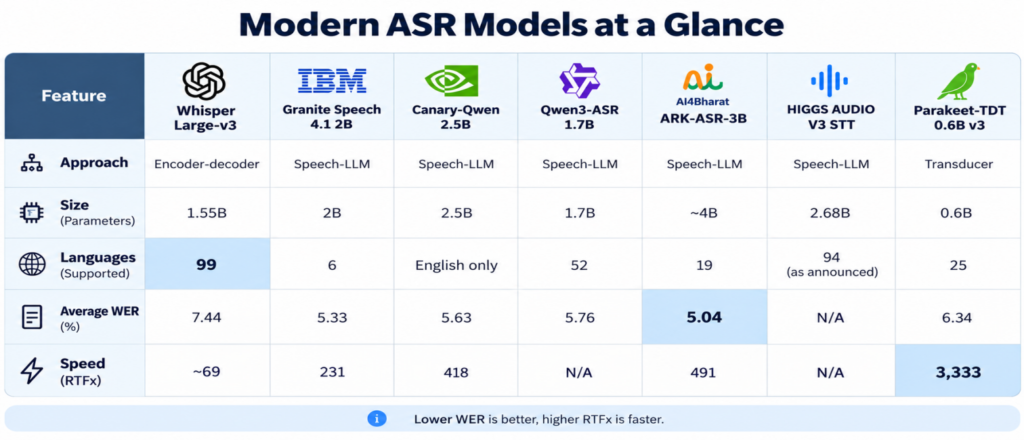
| Feature | Whisper v3 | Granite 4.1 2B | Canary-Qwen 2.5B | Qwen3-ASR 1.7B | ARK-ASR 3B | HIGGS V3 STT | Parakeet 0.6B v3 |
|---|---|---|---|---|---|---|---|
| Approach | Encoder-decoder | Speech-LLM | Speech-LLM | Speech-LLM | Speech-LLM | Speech-LLM | Transducer |
| Size | 1.55B | 2B | 2.5B | 1.7B | ~4B | 2.68B | 0.6B |
| Languages | 99 | 6 | English only | 52 | 19 | 94 (claimed) | 25 European |
| Training data | ~5M hours | ~174K hours | Not detailed | Not detailed | Not detailed | Not detailed | 670K+ hours |
| Licence | MIT | Apache 2.0 | CC-BY-4.0 | Check card | Apache 2.0 | Varies | CC-BY-4.0 |
| Avg WER | 7.44 | 5.33 | 5.63 | 5.76 | 5.04 | N/A | 6.34 |
| RTFx | ~69 | ~231 | ~418 | N/A | ~491 | N/A | ~3,333 |
| Live use | Chunked only | Not documented | Not native | Streaming | Not documented | Verify | Streaming |
| Standout | Translation, language detection | Keyword biasing | Summarises transcripts | Timestamps, dialects | Lowest error | Thinking mode | Fastest, smallest |
| Limit | May hallucinate in silence | Few languages | English only | Mostly English and Chinese tests | Owner-reported | Little independent evidence | No Indian languages |
| Best for | Multilingual, subtitles | English with special terms | English plus text analysis | Multilingual with timestamps | Fast English | Trials | High-volume audio |
| Approach | Encoder-decoder |
| Size | 1.55B |
| Languages | 99 |
| Training data | ~5M hours |
| Licence | MIT |
| Avg WER | 7.44 |
| RTFx | ~69 |
| Live use | Chunked only |
| Standout | Translation, language detection |
| Limit | May hallucinate in silence |
| Best for | Multilingual, subtitles |
| Approach | Speech-LLM |
| Size | 2B |
| Languages | 6 |
| Training data | ~174K hours |
| Licence | Apache 2.0 |
| Avg WER | 5.33 |
| RTFx | ~231 |
| Live use | Not documented |
| Standout | Keyword biasing |
| Limit | Few languages |
| Best for | English with special terms |
| Approach | Speech-LLM |
| Size | 2.5B |
| Languages | English only |
| Training data | Not detailed |
| Licence | CC-BY-4.0 |
| Avg WER | 5.63 |
| RTFx | ~418 |
| Live use | Not native |
| Standout | Summarises transcripts |
| Limit | English only |
| Best for | English plus text analysis |
| Approach | Speech-LLM |
| Size | 1.7B |
| Languages | 52 |
| Training data | Not detailed |
| Licence | Check card |
| Avg WER | 5.76 |
| RTFx | N/A |
| Live use | Streaming |
| Standout | Timestamps, dialects |
| Limit | Mostly English and Chinese tests |
| Best for | Multilingual with timestamps |
| Approach | Speech-LLM |
| Size | ~4B |
| Languages | 19 |
| Training data | Not detailed |
| Licence | Apache 2.0 |
| Avg WER | 5.04 |
| RTFx | ~491 |
| Live use | Not documented |
| Standout | Lowest error |
| Limit | Owner-reported |
| Best for | Fast English |
| Approach | Speech-LLM |
| Size | 2.68B |
| Languages | 94 (claimed) |
| Training data | Not detailed |
| Licence | Varies |
| Avg WER | N/A |
| RTFx | N/A |
| Live use | Verify |
| Standout | Thinking mode |
| Limit | Little independent evidence |
| Best for | Trials |
| Approach | Transducer |
| Size | 0.6B |
| Languages | 25 European |
| Training data | 670K+ hours |
| Licence | CC-BY-4.0 |
| Avg WER | 6.34 |
| RTFx | ~3,333 |
| Live use | Streaming |
| Standout | Fastest, smallest |
| Limit | No Indian languages |
| Best for | High-volume audio |
Challenges and Practical Considerations
Even the best models are not perfect. Noise, overlapping speakers, and poor microphones still cause errors, and code-mixing, such as switching between English and a regional language mid-sentence, remains hard. Rare names and technical terms are often misspelt. Some models hallucinate words during silence, so trim silent parts first. Speech also carries personal data, so consider privacy and licensing. The safest approach: shortlist two or three models and test them on your own audio sample.
Applications and Future of ASR
ASR already powers voice assistants, dictation, captions, and call-centre analytics, supports doctors, lawyers, and journalists, and improves accessibility. Ahead, speech and language models are merging, so one system can transcribe, translate, summarise, and answer questions about audio. These capabilities can also become part of AI agent systems that interact with users and execute tasks. Smarter training helps small models match large ones, and on-device transcription is becoming practical. The biggest gap remains regional and low-resource languages, including many Indian languages, where much of the next progress is expected.
Conclusion
ASR has moved from hand-built parts to single models, and now to speech-language models that pair an audio encoder with an LLM. Whisper remains the broad, mature multilingual choice, newer models show how LLM decoders improve accuracy, and Parakeet proves a small transducer can be extremely fast.
There is no single best model for everyone. The right choice depends on your languages, your audio, and whether you value accuracy, speed, or flexibility. Leaderboards are a good starting point, but the most reliable test is always your own audio.
Frequently Asked Questions
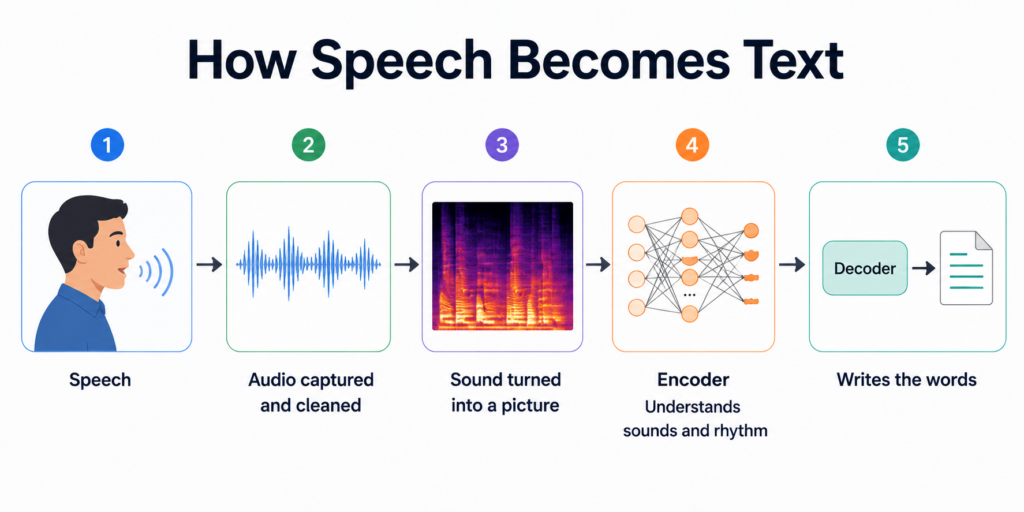
An ASR system processes audio, converts it into a representation such as a spectrogram, uses an encoder to identify speech patterns, and then generates text through a decoder, transducer, or language model.
The three major ASR architectures are encoder-decoder models, transducer models, and speech-language models. Encoder-decoder models process audio before generating text, transducers can generate text while audio is still being processed, and speech-language models connect a speech encoder with a large language model.
WER, or Word Error Rate, measures the number of word-level errors in an ASR transcript. A lower WER generally indicates better transcription accuracy.
RTFx measures how many times faster than real time an ASR model can process audio. A higher RTFx indicates faster processing and can be useful when comparing models for high-volume transcription.
The right ASR model depends on factors such as language coverage, transcription accuracy, audio conditions, processing speed, streaming requirements, hardware, and deployment needs. Testing shortlisted models on your own audio is the most reliable way to evaluate them.